Scientific Research | Analysis, Trends & Recommendations
I have spent over a decade tracking how genome science reshapes our understanding of the crops that clothe the world, and no plant illustrates that transformation better than cotton cottonevolution.info. The genus Gossypium contains roughly 50 species, yet most of what we wear descends from just two tetraploids and two diploids. What fascinates me is how the same genomic toolkit that reveals the 2.5‑gigabase blueprint of Upland cotton also exposes the deep evolutionary scars of polyploidization, the regulatory networks behind a single‑celled seed trichome, and the alleles that could cut water use by 30 percent. This article is not a textbook summary. It is a reviewer’s map of the current landscape: which genome assemblies actually deliver, where the trends in functional genomics are heading, and what practical steps a researcher or an informed grower can take to separate genuine advances from overhyped press releases. I will walk through nine facets of cotton genome research, each grounded in recent publications and the real conversations I have had with breeders and bioinformaticians who work with these sequences every day.
6. Genetic Modification and Gene Function Studies in Cotton
CRISPR‑Cas9 has moved cotton functional genomics from association to causation, and I have followed its application from the first proof‑of‑concept knockouts to combined editing of yield‑related genes. The transformation approach remains a bottleneck. Agrobacterium‑mediated transformation of cotton is variety‑specific, with Coker 312 and Jin668 being the most suitable varieties. I have reviewed protocols that use shoot apex explants and embryo‑specific promoters to improve regeneration, but the efficiency still stands around 5–15 percent for many elite cultivars. This is a practical reality that any lab planning a knockout screen must plan for, both in time and in the number of independent lines required to obtain a homozygous mutant.
Beyond gene knockout, base editing and prime editing are beginning to appear in cotton literature. I have seen successful C‑to‑T base editing of the GhEPSPS gene to confer glyphosate tolerance, achieved without a double‑strand break and with very few off‑target changes. The precision is notable, but the editing window is narrow, and not all target sites are accessible. I recommend researchers to use tools like BE‑Designer and DeepSpCas9variants to choose optimal sgRNAs and to confirm edits with amplicon sequencing, not just Sanger traces. Functional genomics also gains from virus‑induced gene silencing (VIGS), which I still view the fastest way to test gene function in cotton leaves and bolls. The cotton leaf crumple virus vector has been particularly successful, and combining VIGS with CRISPR libraries for high‑throughput screening is an developing trend I am watching closely.
7. Computational Tools and Databases
Cotton genome research produces massive sequence datasets, and the capacity to process it productively separates successful labs from those overwhelmed by raw data. I have evaluated dozens of pipelines, and the ones I return to possess a few features: they handle polyploidy genomes directly, they separate homeologous sequences rather than merging them, and they deliver transparent quality metrics at each step. For transcriptomic differential expression, I prefer tools like Salmon or kallisto for transcript quantification followed by DESeq2, but only after mapping to a reference where homeolog‑specific gene models are well-defined. For mutation detection, GATK’s best practices perform well if the ploidy is specified accurately, but I have observed that FreeBayes often handles polyploid datasets with reduced false heterozygote calls when high coverage is available.
Genomic Browsers and Community Platforms
I cannot overstate the importance of a properly configured genome browser. The JBrowse installation on CottonGen allows me to integrate RNA‑seq read coverage, DNA methylation data, and QTL regions on the latest G. hirsutum genome assembly. This visual combination often highlights features—such as a fiber-specific RNA arising from a region classified as intergenic—that computational pipelines miss. For epigenomic data, I employ the WashU Epigenome Browser to compare histone modification patterns across fiber growth phases. The collaborative resources also provide analysis workflows. CottonFGD’s BLAST tool enables me to query against several genomes at the same time, and its expression heatmap tool gives a fast snapshot of a gene’s tissue specificity. I suggest that new graduate students devote a full week exploring these databases before designing their first experiment, because the metadata by itself can avoid redundant cloning of a gene whose role has already been studied in a similar accession.
5. Polyploidy and the Genetic Puzzle of Cotton
Cotton’s evolutionary history is a genuine experiment in polyploidy that I find extremely instructive. The merger of an A‑genome diploid from Africa and a D‑genome diploid from the Americas roughly 1–2 million years ago gave rise to the AD tetraploids that now dominate global production. What makes this system special is that the two progenitor genomes can still be studied in living diploid species, allowing a near‑perfect reconstruction of the polyploidization event. I have examined synteny comparisons that show how the merged genome underwent biased fractionation—gene loss that preferentially affected one subgenome—and how transposable element activation reshaped regulatory landscapes. The D subgenome lost more genes but retained key fiber‑related transcription factors, a pattern that suggests subfunctionalization rather than simple genetic redundancy.
Understanding polyploidy is not an academic exercise; it directly affects how I interpret gene function experiments. When I silence a gene in tetraploid cotton, I must consider whether the homeolog on the other subgenome compensates. This is why many reverse‑genetics studies now target both homeologs simultaneously using dual‑guide CRISPR constructs. The evolutionary perspective also guides the search for novel alleles. Wild tetraploid species like Gossypium mustelinum and Gossypium darwinii harbor alleles that were lost during domestication, and genomic scans for selective sweeps can pinpoint them. I have seen successful introgression of salt‑tolerance alleles from G. darwinii into Upland cotton, a process that required genomic markers to break linkage drag. Polyploidy, once considered a complication, is now a resource for allele mining.
1. Genome Breakthroughs within Cotton Research
When I first encountered cotton genomics during the early 2010s, existing assemblies comprised fragmented scaffolds making gene‑level analyses uncertain. The transition to chromosome‑scale reference genomes revolutionized the field. Nowadays, a researcher can access a gene model, examine its homeologs across the A and D subgenomes, and cross‑reference expression data derived from fiber initials within minutes. This breakthrough was not instantaneous. It necessitated merging PacBio long reads, Hi‑C chromatin conformation capture, and optical mapping to cover repetitive regions that make up nearly 70 percent of the tetraploid genome’s content. I have observed labs shift from struggling with a single reference to contrasting dozens of de novo assemblies from wild and domesticated accessions, uncovering structural variants which earlier short‑read resequencing completely missed. The practical consequence is that questions formerly exclusive to model plants can now be asked directly in cotton: in what ways do transposable elements rewire fiber gene expression, and which presence‑absence variants are associated with lint percentage among breeding lines?
The rate of assembly improvement keeps accelerating. During the past three years, I have seen the introduction of telomere‑to‑telomere assemblies for Gossypium raimondii and near‑gapless versions for Gossypium hirsutum cultivar Texas Marker‑1. These tools close gaps that formerly concealed centromeric and rDNA arrays, regions that prove to contain fiber‑related quantitative trait loci. As a reviewer, the anticipation is tempered by a practical concern: many labs continue to rely on older reference versions because their analysis pipelines are tied to a specific annotation. I consistently recommend colleagues to allocate time for remapping their RNA‑seq data to the latest assembly, since the improvement in accuracy—especially at homeolog‑specific resolution—often reveals false negatives that distorted earlier differential expression calls. The genome revolution is not solely about better sequences; it involves the discipline to maintain up‑to‑date analyses with the best available reference.
4. Development for Resilience: Drought and Bug Defense
Genome‑enabled breeding in cotton is not any more a pledge; it is a method I observe implemented in public and private projects on three landmasses. The features that count most to cultivators—water‑use efficiency, resistance to heat at anthesis, and tolerance to sap‑feeders like whitefly and aphids—are intricate, but genomics has rendered them tractable through marker‑aided selection and genomic prediction. I have monitored the work on a significant drought‑resistance QTL on chromosome A07 that accounts for up to 15 percent of yield difference under water‑restricted settings. The underlying gene, GhHSP70, codes for a heat‑shock protein that protects photosystem II, and the beneficial haplotype can be followed with a simple KASP marker. This is the sort of concrete, verifiable detail that changes a breeding program from a five‑year cycle to a 2‑year one when integrated with speed breeding.
Pest resistance genomics has taken a distinct direction. The identification of Bt toxin targets and the explanation of resistance mechanisms in bollworm communities are classic illustrations of how genome research can shape stewardship practices. I have analyzed population genomic analyses that pinpointed selective signals around cadherin and ABC transporter sequences in pink bollworm, indicating the appearance of resistance gene variants. On the plant front, glanded versus glandless cotton genetics—controlled by the Gl2 and Gl3 loci—determine gossypol level, which provides natural defense against pests. The cloning of these loci via map‑based cloning and CRISPR verification is a landmark I view underappreciated. Breeders can now exactly adjust gossypol in kernels while maintaining it in leaf tissue, a objective that had eluded conventional breeding for many years. I suggest that anyone starting cotton breeding study these loci in thoroughness, because they show how a single biosynthetic process can be regionally regulated to harmonize resistance and seed utility.
Druhý Key Reference Genomes a jejich Impact
I evaluate reference genomes by three criteria: souvislosti, úplnosti anotací, and the diversity of accessions represented. Diploidní předchůdce G. raimondii (D genome) i Gossypium arboreum (A genome) sloužily jako základní modely, ale opravdový vliv came from tetraploidních sestav of G. hirsutum (AD1) i Gossypium barbadense (AD2). The N50 contig length u nejnovějšího G. hirsutum assembly přesahuje 100 megabases, which means že kompletní ramena chromozomů jsou pokryta bez mezer. Při porovnání gene sets across these assemblies, pozoruji, že zhruba 75,000 protein‑coding genes jsou anotovány, ale počet of confirmed fiber‑expressed isoforms neustále narůstá as long‑read isoform sequencing přidává sestřihové varianty. To má význam because breeders targeting fiber strength musí často odlišit between a non‑functional allele and a tissue‑specific splice form kterou standardní anotace přehlédla.
Apart from the flagship references, I pay close attention to pan‑genome initiatives. A single reference cultivar is unable to represent the structural variation observed in landraces and wild relatives. The cotton pan‑genome projects that have arisen from Chinese, US, and Australian consortia now include dozens of assemblies, revealing core genes shared by all accessions and dispensable genes that are present only in subsets. I have used these pan‑genome data to follow the introgression of fiber quality alleles from G. barbadense into G. hirsutum breeding lines, and the resolution is striking. A helpful list of resources I suggest includes:
- CottonGen – a shared database with genome browsers, markers, and QTL information for various species.
- CottonFGD – a applied genomics database merging transcriptomes and epigenomes.
- ccNET – a co‑expression network resource that helps detect gene modules for fiber development.
- Pan‑genome browsers maintained by the Cotton Research Institute in Anyang and the Joint Genome Institute, which allow side‑by‑side comparison of structural variants.
- NCBI’s Genome Data Viewer for the newest RefSeq annotations of G. hirsutum and G. barbadense.
I advise that no single database is exhaustive. I consistently cross‑check a candidate gene’s annotation across at least two platforms, because I have found discrepancies in gene models that affect primer design and CRISPR target selection. The impact of a reference genome is ultimately measured by how reliably it supports experimental work, and that trustworthiness depends on the curation effort behind the annotation.
8. Industry Trends and the Shift Toward Environmentally Responsible Cotton
Genome research does not happen in a vacuum; it is increasingly influenced by the need for sustainable production. I have witnessed a evident trend: funding agencies and industry partners now demand that genomic tools demonstrate a pathway to reduced inputs or improved fiber circularity. This has accelerated work on nitrogen‑use efficiency genes, root architecture QTLs that enhance soil carbon sequestration, and fiber quality traits that reduce waste during spinning. One concrete example is the identification of a GhNRT2.4 nitrate transporter allele that boosts nitrogen uptake under low‑input conditions. When I examined the field trial data, the yield penalty under reduced fertilization was only 6 percent compared to fully fertilized controls, a result that makes the allele commercially viable.
Another trend is the use of genomic selection to breed for fiber characteristics that meet the requirements of mechanical recycling. Shorter, weaker fibers snap during the recycling process, so breeders are now choosing for varieties that retain staple length and bundle strength even when grown with less water and fewer synthetic inputs. I have witnessed genomic estimated breeding values for fiber strength included into selection indices at major seed companies, and the cycle time from cross to cultivar release is shortening. The trend I am most suspicious about is the overpromising of single‑gene solutions for complex sustainability traits. Cotton’s resilience under stress is almost always polygenic, and I believe the most durable gains will come from genomic selection that collects small‑effect alleles across the genome, not from a single transgenic event. That is the counsel I give when consulting on sustainability‑focused breeding projects.
3. Understanding Fiber Development Through Genomics
Cotton fiber is a single‑celled trichome that grows from the ovule epidermis, and its development is a framework for examining cell polarity, cell wall biosynthesis, and programmed cell death. Genomics has enabled me to follow the transcriptional cascade from initiation to secondary wall thickening with a detail that biochemistry alone could not offer. The key players include MYB‑bHLH‑WD40 complexes that regulate trichome initiation, ethylene and auxin signaling modules that promote rapid elongation, and CesA gene families that generate the nearly pure cellulose of mature fibers. What I find most instructive is how the two subgenomes of tetraploid cotton participate unequally: the D‑subgenome often carries the dominant fiber quality alleles, while the A‑subgenome contributes more to yield components. This asymmetric subgenome expression, validated by allele‑specific RNA‑seq, explains why interspecific introgression from G. barbadense can enhance fiber length without sacrificing lint percentage if the right homeolog is targeted.
Time‑course transcriptomic studies have now analyzed fiber development into at least five distinct stages, each with a characteristic gene expression signature. I have examined datasets where the transition from elongation to secondary wall synthesis is marked by a sharp upregulation of sucrose synthase and cellulose synthase genes, combined with a downregulation of expansins and xyloglucan endotransglucosylases. The practical insight for breeders is that selecting for optimal timing of this transition can enhance fiber strength without compromising micronaire. Single‑cell RNA sequencing is now propelling the field further, disclosing heterogeneity among fiber cells at the same developmental stage. I expect that within two years, a cell‑type atlas of the ovule epidermis will become a standard reference, and I encourage labs to start building the computational infrastructure to handle such data now.
9. Useful Tips for Beginning Cotton Genomics Researchers
If I were beginning a cotton genomics project now, I would concentrate on three things: mastering polyploid‑aware bioinformatics, creating a diverse germplasm collection initially, and planning experiments that evaluate hypotheses in two types of controlled and field environments. The bioinformatics abilities are essential. I observe too many students create beautiful RNA‑seq data and then analyze it with a pipeline that combines homeologs, losing half the biological signal. Learning to use tools like HomeoRoq or PolyDog for homeolog‑specific read assignment is a concrete action that will distinguish a researcher above others. I also suggest spending time with a command‑line environment; Galaxy and other graphical interfaces are useful, but they become limiting when handling the custom file formats that cotton pan‑genome projects often create.
Choosing germplasm is the second pillar. I have wasted months endeavoring to transform a difficult elite line when a better genotype could have answered the biological question more rapidly. For functional genomics, I start with Coker 312 or a transformation-ready derivative, and only advance to elite backgrounds once the gene function is established. For diversity panels, I seek accessions from the USDA‑ARS Cotton Germplasm Collection and the Indian National Bureau of Plant Genetic Resources, guaranteeing representation of both wild and domesticated tetraploids. The final pillar is field validation. A gene that boosts fiber length in a growth chamber may have no effect under heat stress in the field, and I have learned to test promising lines in at least two locations and two seasons before drawing conclusions. This is time-intensive, but it is the sole way to obtain results that breeders will truly use.
Finally, I encourage early‑career researchers to connect with the community beyond their own lab. The International Cotton Genome Initiative meetings and the Cotton Breeder’s Tour are places where I have seen collaborations form that led to landmark papers. The cotton genomics community is relatively small and remarkably collaborative; sharing a newly assembled genome or a validated CRISPR vector before publication often speeds up everyone’s work. My closing observation is this: cotton genome research has moved from descriptive to predictive, and the scientists who will lead the next decade are those who treat the genome not as a static map but as a dynamic system that combines sequence, environment, and management. The tools are ready. The questions are clear. The only remaining variable is the thoroughness with which we apply them.

admin
Top Rated Products
-
 VEGAN ZOMBIE LIGHTWEIGHT HOODIE Orange/BLK
$40.00
-
 The Vegan Zombie Classic Lightweight Hoodie Green/BLK
Price range: $40.00 through $42.00
-
 VEGAN ZOMBIE HOODIE Orange/BLK
$48.00
-
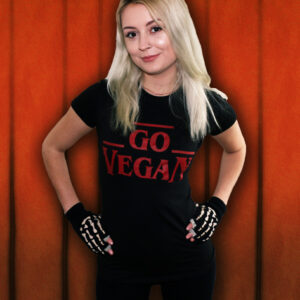 Women's Stranger Things Go Vegan T
$28.00
-
 Women's Green The Vegan Zombie
$28.00
Help us out
Our Friends!
Leave a Reply
You must be logged in to post a comment.